

Imagine asking an AI assistant about a trip you’re planning. It might remember that you prefer to travel by train, notice that the trip you mentioned last month has already happened, and quietly update its notes so you don’t have to explain it all again.
Now imagine a robot reaching for a cup. Before its gripper moves, a model generates a possible continuation of the scene: the arm approaches, the fingers close, the cup lifts. If that imagined future looks wrong, the robot has a chance to do something else.
And then there’s a third system, generating imaginary experiences of its own, not to entertain us with convincing pictures, but to find useful things it might learn.
All three are being now being described as dreaming.
That’s a strange word to find in serious AI research. But it’s showing up in increasingly interesting places, and I don’t think it’s just a cute metaphor borrowed from neuroscience. I think it points towards something deeper about how generative AI is evolving.
The tempting story is that we’ve moved from models that generate, to models that reason, and now to models that dream. I think there’s something useful in that progression. But the more interesting story might be that all three are variations of the same underlying activity, operating on increasingly rich and better-grounded internal representations.
Three very different kinds of dreams
In June 2026, OpenAI published a piece explicitly called Dreaming: Better memory for a more helpful ChatGPT. The idea is that an assistant shouldn’t simply accumulate scraps of information from old conversations. It should revisit them, connect related details, notice when something has become stale, and prepare more useful context for the next interaction.
Anthropic’s November 2026 discussion of the components of agent memory takes a similar idea further. It describes agents revisiting their transcripts to correct mistaken notes and build interconnected memory representations. One of their examples is completely mundane: a Claude agent playing Pokémon had remembered a location incorrectly. An offline dreaming pass checked the original transcript, repaired the note, and that changed what the agent did next.
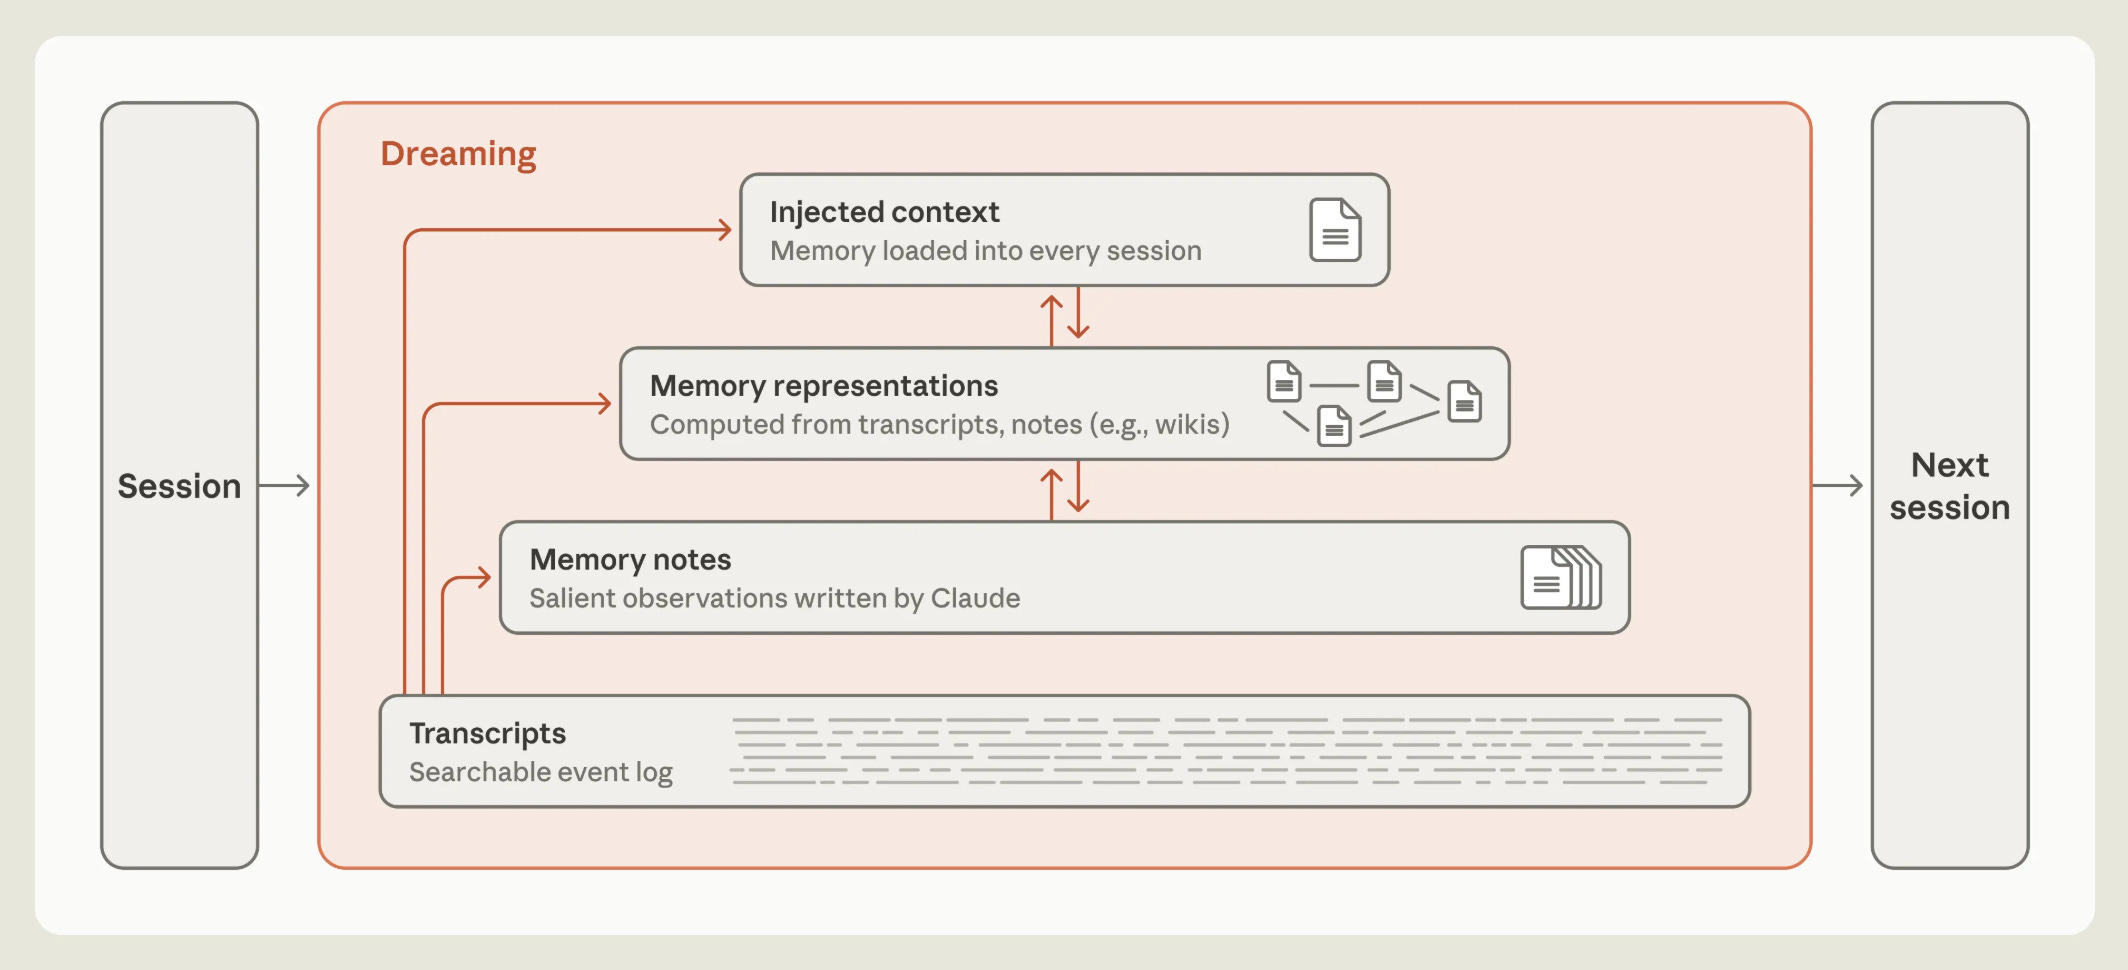
This kind of dreaming looks a lot like reflection. The agent isn’t inventing a new world. It’s trying to make better sense of the one it has encountered. It’s reconciling a remembered account of events with the available record.
There’s an obvious biological analogy here, although need to be careful with it. Human memory processing involves both wakeful reflection and sleep-dependent consolidation, including important roles for NREM and REM sleep. But an AI system doesn’t need to be asleep, or conscious, for an analogous organisational process to be useful. The important part is the work being done on memory when the original event is no longer taking place.
Now let’s shift to a robot reaching for that cup.
Dream Labs’ Dream-1, announced in October 2026, belongs to an emerging family of World Action Models. Instead of only predicting an action, such a model learns to predict future video and actions together. The imagined scene and the movement needed to produce it become part of the same problem. Dream-1 returns short segments of robot actions, which can be repeatedly updated as fresh camera observations arrive.
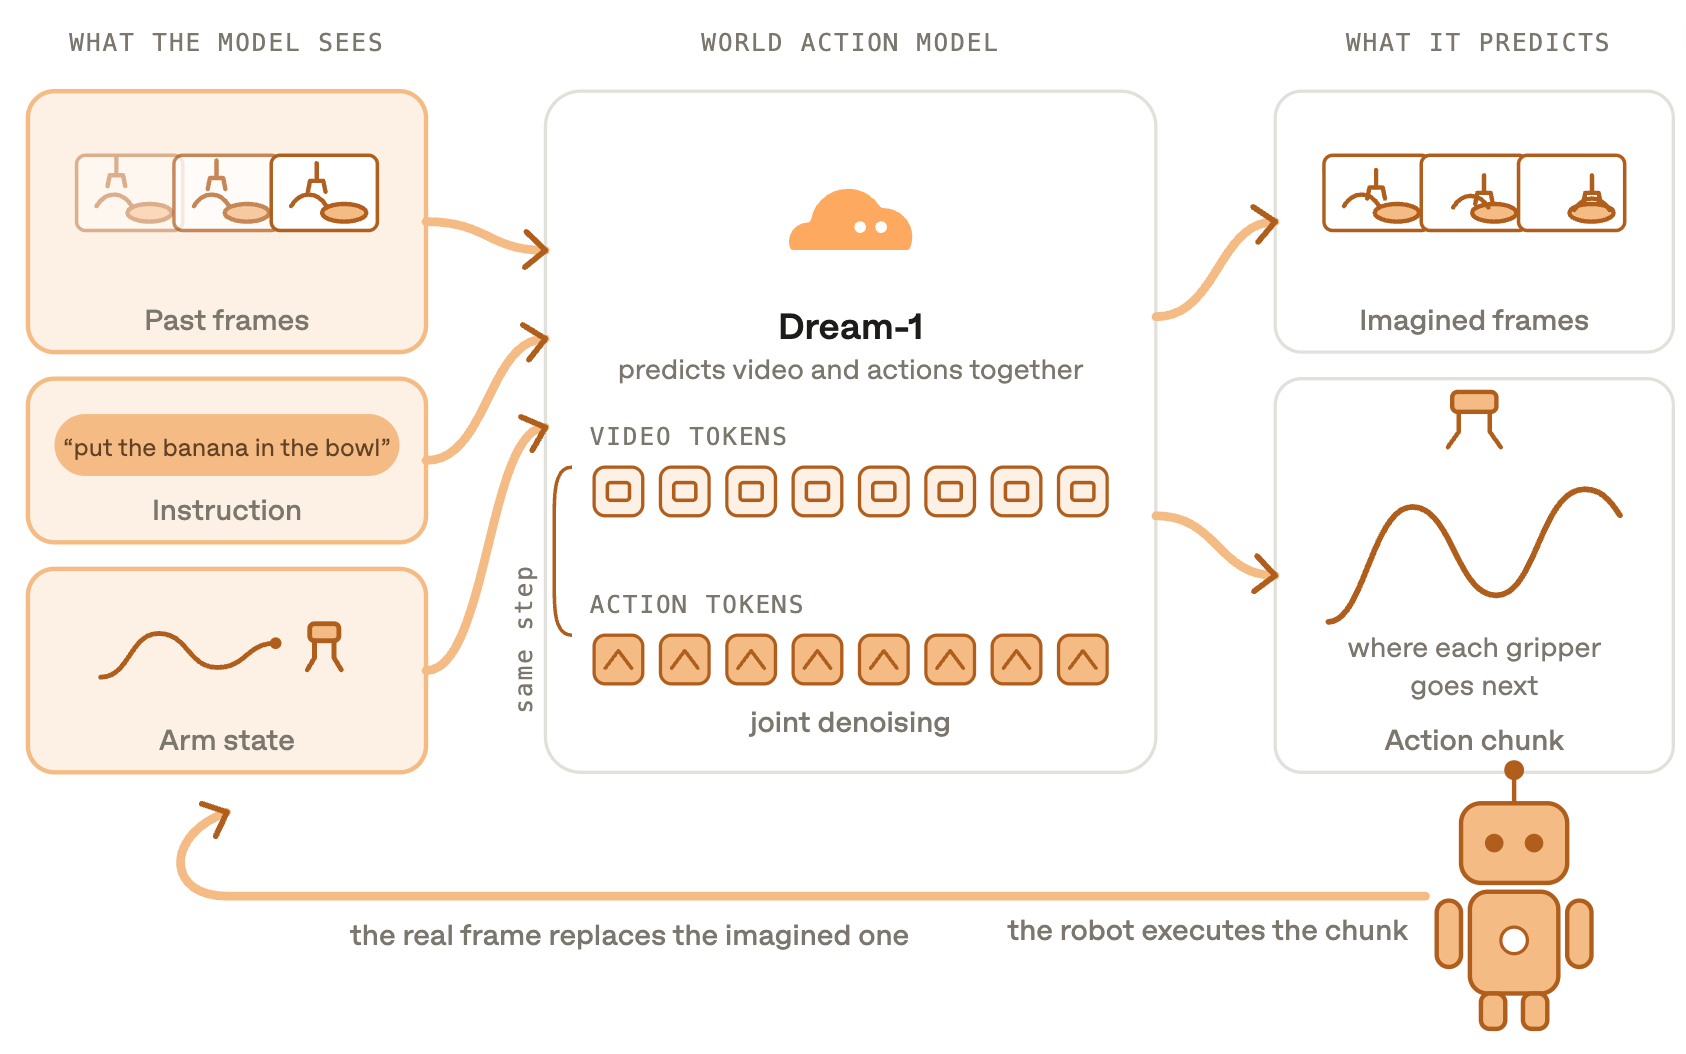
This is a very different dream. It’s closer to anticipation, or the quick little simulations we run when we reach to catch something falling off a table. What might happen next if I move this way rather than that way? In robotics the imagined future needs to stay tightly coupled to what the cameras and sensors are actually showing, because the cup is not going to forgive an elegant but physically impossible prediction.
And then there’s the more open-ended kind. In October 2026, Google Research described a sleep framework for continual learning that distinguishes consolidation from dreaming. Here dreaming means generating synthetic experiences, selecting useful ones, and using them for further training. It’s closer to rehearsal, ideation or exploration. The system isn’t necessarily trying to predict the next event in an existing scene. It is constructing possibilities it can learn from.
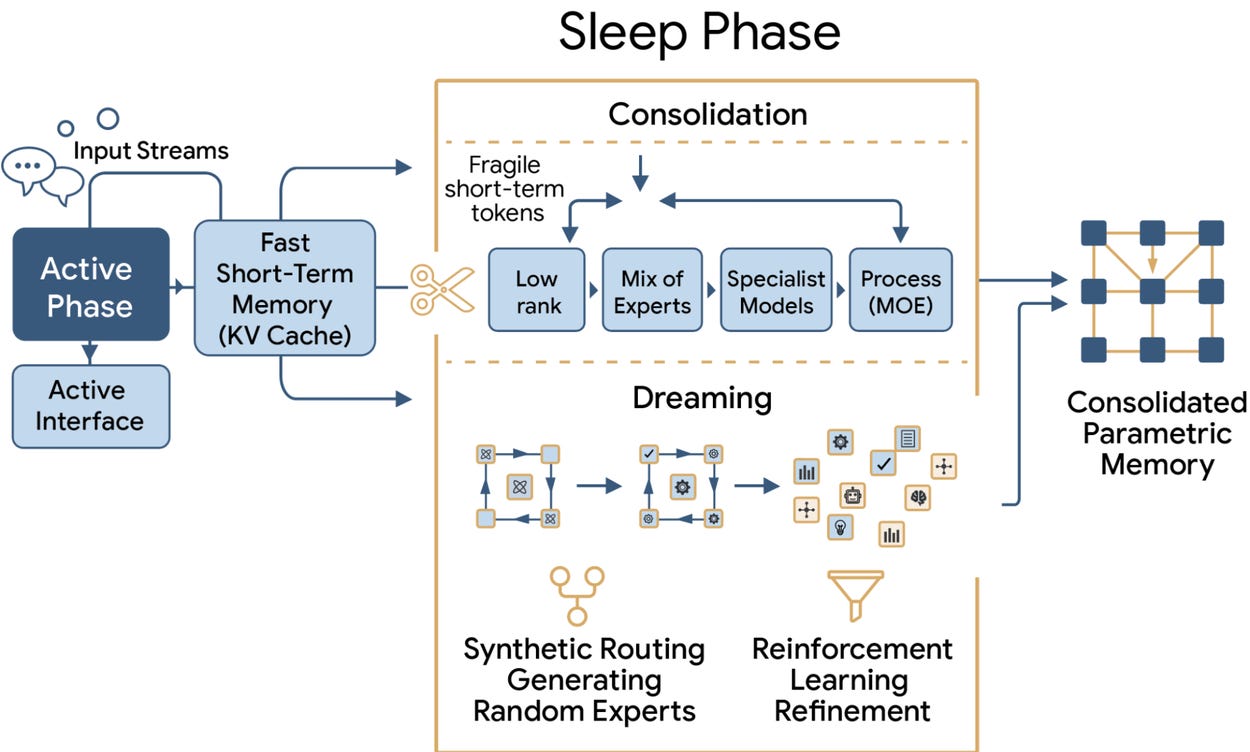
The approaches are technically very different. Some change an external memory store. Some predict trajectories or actions. Some propose updates to model weights. It would be a mistake to treat them as one algorithm.
But viewed from a little further back, I think they share a family resemblance.
Dreaming is a family of internally generated cognitive processes that
reconstruct, reconcile, simulate or extend an internal model of the world,
with varying degrees of grounding, temporal orientation and deliberate control.
Reflection looks backwards. Anticipation looks forwards. Imagination asks what else might be possible. Scenario planning can even feel like a kind of wakeful lucid dreaming, where we deliberately hold a possible world in mind and change its conditions to see what follows. None of these needs sleep, and none needs to imply subjective experience.
What matters is that the system can work with an internally constructed representation when the thing being represented is not directly in front of it.
Generation, reasoning and now dreaming
This is where I think the story gets more interesting.
The first wave of modern generative AI showed us systems that could produce extraordinarily plausible continuations. Large language models used autoregressive next-token prediction. Image and video systems used techniques including diffusion. They learned statistical and semantic structure from enormous training corpora, and that structure made it possible to generate things nobody had explicitly written or pictured before.
You could call this useful hallucination, provided we’re careful about the word. Generation is not inherently an error. It’s an ability to produce a plausible possibility from a learned distribution. A hallucination only becomes a problem when that generated possibility is presented as though it were an observed or verified fact.
The crucial point is that these models were never simply copying fragments of their training data. Their learned representations already carried rich information about objects, relationships, people, roles, situations and how language describes the world. In a text-first interaction, though, the new evidence available during a session was mostly the prompt and conversation context, including the model’s own tokens that were generated earlier. A user’s statement is an observation that the user said something, not independent confirmation that the world is as they described it.
Reasoning models then added another layer. Instead of moving straight from question to answer, they can spend additional computation exploring intermediate steps, testing candidate interpretations and revising a proposed solution. Some of this is expressed in generated reasoning tokens. Some is mediated by internal activations we don’t read directly. In either case, reasoning remains closely tied to the generative process. It isn’t a little rational homunculus operating outside the neural network.
So if generation produces possible continuations, reasoning gives the system more opportunities to evaluate and constrain those continuations before committing to an answer.
Dreaming then looks like a further expansion of what those internally generated representations are for. Rather than only helping construct the next answer, the system can revisit a history, maintain an evolving account of a situation, rehearse an action, or explore a counterfactual future. It can sometimes compare the result with later observations and use the discrepancy to update its context or behaviour.
That gives us a useful shorthand:
Generation → Reasoning → Dreaming
Not a strict historical sequence, and certainly not three cleanly separated pieces of machinery. World-model research and imagined rollouts predate today’s reasoning models. But as a picture of the expanding scope of generative cognition, I think it’s quite powerful.
We’re moving from generating plausible representations, to reasoning over representations, to maintaining and evolving models of an observed world.
There is one catch, though. It would be wrong to imagine that world models only arrived with this latest wave of research.
Self, Other and World were already in the room
Think about what happens when you write to a language model:
“You are the interviewer. I’m the candidate. Ask me about my last project.”
Before it can sensibly respond, the model has to maintain some working distinction between you, me, the roles we’ve assigned, the project we’re discussing, and the implied situation. If we swap the roles in the next turn, it has to update that arrangement. Change a pronoun or move a role instruction and the behaviour can shift dramatically.
This is the territory I’ve explored in my earlier work on the three-process view of latent models and what I call Latent Deictic Models (LDMs). Deixis is simply the way words such as I, you, here, there, now and then depend on a point of reference. An LLM needs working representations of those relationships to do even fairly ordinary conversational work.

That gives us a minimal, non-anthropomorphic sense in which the model is doing some self-modelling. It represents its own conversational role and constraints. Shift the centre of perspective to the human interlocutor and we’re in the territory of other-modelling. Keep expanding the situation and we encounter objects, places, institutions, actions, causes and consequences. That’s already a foothold in world-modelling.
I’m not suggesting that all these models are equally developed, or that one must evolve into the next. A robot can learn useful physical dynamics without first learning the pronouns I and you. And an LLM’s competent conversation about a falling cup doesn’t establish that it has a reliable physics simulator.
My point is narrower and, I think, more interesting. The LLM training corpus has always been saturated with descriptions of selves, others and worlds. The model already needs to recruit some of that structure to generate coherent responses. Fine-tuning and preference-based training help shape how it uses those representations in interaction, while each new prompt changes the immediate context it’s operating within.
So dreaming doesn’t necessarily introduce the first world model. It extends how situated latent models are used, especially their ability to persist across interactions, accommodate new observations, and support predictions that can be checked against what happens next.
That distinction matters. It turns an apparent technological discontinuity into a story about an evolving capability that was already there in a more limited form.
Grounding the dream
A model can tell a beautifully coherent story about a cup floating gently into the air. Coherence alone won’t keep the cup from falling off the table.
I’ve been thinking about three qualities that are too often bundled together.
Internal coherence asks whether the imagined scenario hangs together on its own terms.
Empirical grounding asks how well it is constrained by available observations.
Predictive validity asks how well its expectations hold up against subsequent observations.
These aren’t the same thing.
An invented city can be internally consistent without existing. A forecast can be scrupulously calibrated to historical data and still be wrong about the next decade. Anyone who has read a ten-year infrastructure forecast will recognise the genre: impressive charts, carefully labelled assumptions, and, if we’re being realistic, an elaborate work of speculative fiction presented with the confidence of a railway timetable.
That doesn’t make modelling useless. It means we need to be clear about which claims are observations, which are assumptions, and which are imagined consequences.
I prefer observed reality or available evidence to the philosophically loaded phrase external truth. An AI system does not get privileged access to reality, and it’s important to note that neither do we. We work with partial observations, instruments, reports, and prior models. So the question is whether an internal representation remains useful when we push against those observations.
The level of grounding also depends on the situation. A robot making a fast movement needs a short, frequently corrected prediction. A planner exploring several alternative designs needs room for counterfactuals. A writer inventing a fictional world can loosen the ties to current observation almost entirely. Yet a long-range forecast with high stakes may require rigorous grounding even though its horizon is far away.
So we can think of dreaming as moving through a space defined by grounding, temporal orientation, deliberate control and counterfactual freedom. A quick physical prediction and a leisurely daydream can be members of the same broad family and likely sharing cognitive machinery, without having the same obligations to evidence.
The difference between productive imagination and a misleading hallucination is not simply whether an internal possibility was generated. It’s what the system does to distinguish that possibility from an observation, and how it tests or qualifies the result.
This also suggests a useful boundary for the term dreaming. If every generated token counts as a dream, the word would tell us very little. Instead, what interests me is when the system generates a representation to operate on it: to inspect, revise, compare, rehearse or project it beyond the immediate input.
World models are getting more explicit
Against that background, the newer world-model research looks less like a sudden departure and more like a deliberate attempt to build stronger versions of these capabilities.
Fei-Fei Li’s June 2026 essay, A Functional Taxonomy of World Models, makes a useful distinction between renderers, simulators and planners. A renderer produces what a scene might look like. A simulator represents structure and dynamics that should keep working when we interact with them. A planner turns observations and goals into actions.
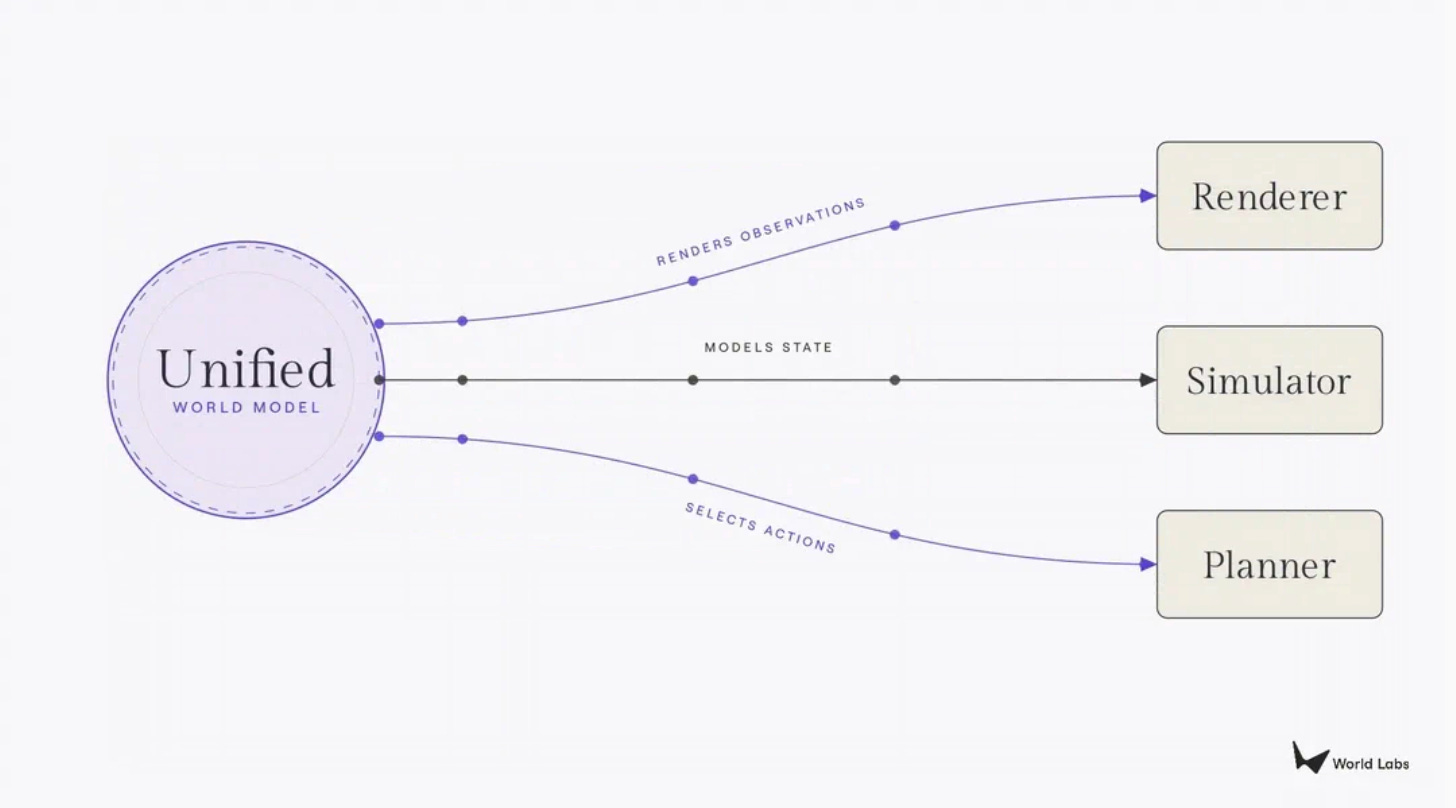
This maps nicely onto our problem. Making a plausible image is not the same as maintaining a consistent world through time. Maintaining that world is not the same as deciding what to do in it. Yet all three might draw on related learned structure, and current research is increasingly joining those functions together.
The robotics work is especially vivid because it makes the cost of a bad dream immediate. A generated video can look wonderful while hiding impossible geometry. A robot using that prediction to pick up a cup quickly discovers the error.
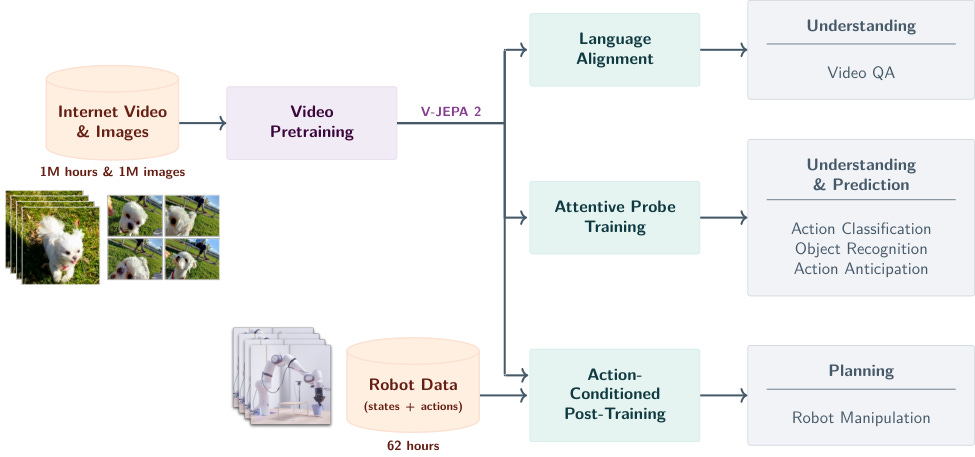
There’s another important distinction here, highlighted by Yann LeCun’s work on JEPA, including V-JEPA 2. The imagined future needn’t look like an image or a film at all. A model can predict in an abstract representation space, learning which aspects of the scene matter most without trying to regenerate every pixel. So dreaming in a latent world model might be largely invisible from the outside.
And this is not a brand-new line of thought. David Ha and Jürgen Schmidhuber’s World Models work in 2018 explicitly explored agents learning in internally generated dream environments. DreamerV3 developed the idea of learning behaviour from imagined trajectories in latent space. Today’s video-rich world action models are another point in a longer research story, not its beginning.
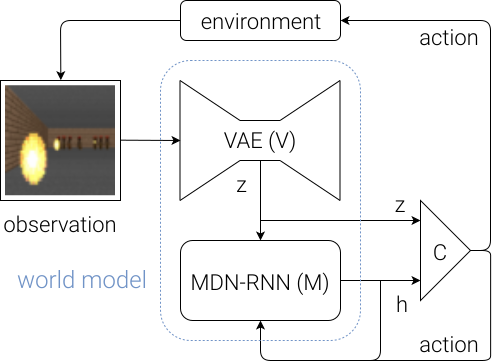
Here, the common ambition is to move from plausible depictions towards internal representations that continue to be useful when the world changes, when actions have consequences, and when fresh observations arrive.
Back to latent models: what’s actually doing the dreaming?
This is where the story connects most directly to my previous posts.
In What is a ‘Latent Model’?, I argued for thinking of a latent model not as a single magical object hidden somewhere in a network, but as a portable internal scaffold. Some parts act like compact states carrying useful variables. Some are routes that recompute relationships as the context changes. Others are anchors that pull the computation back towards earlier information. The relative influence of these processes is what I’ve been calling arbitration.
That’s a conceptual and mechanistic lens, not a claim that we’ve already found one universal circuit for world-modelling. But it gives us a productive way to ask what dreaming might involve inside generative systems.
When an agent reflects on an earlier conversation, which states does it recover? Which routes does it recompute? What observations does it treat as anchors when two memories disagree? When a robot imagines the next few moments, which latent variables have to remain stable, and which are allowed to change? When a model explores a creative counterfactual, how does the balance shift between established structure and newly generated possibilities?
The answers won’t necessarily look the same in an LLM, a video model and a robot controller. Still, these are more useful questions than imagining a single gigantic world model being consulted as though it were a reference book.
There’s a related thread in Do NOT Think Of A Polar Bear!. A model can carry an internal representation without putting it directly into its output. That separation between what is represented, what influences computation, and what finally gets expressed matters enormously here. Dreaming doesn’t have to appear as a narrated dream like a “Chain of Thought”. An internal state can shape an action or an answer without ever becoming a visible scene.
Recent Goodfire research provides interesting, but still provisional, context for this view too. Its work on neuron communities investigates groups of neurons that jointly support recurring behaviours. Neural Networks Are Already Clean argues, as a working hypothesis, that some apparently tangled representations may have more interpretable organisation than we thought. And mechanistic shaping explores influencing the internal representations a model relies upon, rather than judging only its outputs.
None of that demonstrates a mechanism for dreaming. It doesn’t prove my arbitration framing either. But it does make the broader question more concrete: what are the reusable internal structures, how are they recruited, and how could they be reactivated or recombined when the system is reflecting, anticipating or imagining?
There’s an equally important caution from my posts on latent models and understanding and why LLMs are both fragile and brilliant. Having a representation is not the same as using it reliably. A system can maintain a coherent perspective for twenty turns and then lose it on the twenty-first. It can simulate a plausible future and fail to notice that the premise was wrong.
Dreaming potentially gives these systems more opportunities to inspect and repair their models. It also gives them more opportunities to reinforce mistakes. Internal rehearsal only becomes useful when something anchors it, challenges it, or helps discriminate between better and worse imagined possibilities.
That may turn out to be the central engineering problem: not just how to generate a possible world, but how to decide which possibilities deserve to influence the next act, the next memory, or the next decision.
When the model starts thinking with its world
I started this post with three quite different dreams: an assistant cleaning up its memories, a robot imagining the next movement, and a system creating synthetic experiences for practice.
They still aren’t one technology. Memory maintenance, predictive control and learning through generated examples have very different architectures, different constraints and different ways to fail. Nor does the word dreaming suggest that an AI system sleeps or experiences anything like a human dream.
But I think the shared idea has real value.
Generative AI began by showing how much structure can be learned from a corpus and expressed as convincing new outputs. Reasoning expanded the ability to work through generated intermediate representations. The new wave of dreaming research extends this into something more situated and, in some cases, more persistent: internal models that can be revisited, projected, challenged and reconciled as the system encounters more of the world.
Seen this way, generation, reasoning and dreaming aren’t
three separate kinds of intelligence. They’re overlapping ways of
operating on learned representations, with growing opportunities
to test those representations against observation.
And perhaps that’s the real shift to watch. Not simply whether AI can produce a believable description of the world, or even an impressive explanation of what might happen next, but whether it can maintain a useful model across time, recognise when that model has gone stale, explore alternatives, and change what it does when observations disagree.
The really interesting thing about dreaming isn’t that AI is becoming more human.
It’s that AI is beginning to use its generated representations as something more than outputs. It’s beginning to use them as worlds in which to think.